Enterprise Knowledge Retrieval (RAG)
Stop guessing. Start knowing. We build secure Retrieval Augmented Generation systems that connect your LLMs to your private data (PDFs, SQL, SOPs) delivering answers that are accurate, citable, and grounded in your enterprise truth.
Why Public LLMs Fail in the Enterprise
Generic Data
Public models don't know your business. RAG bridges the gap by injecting your private contracts, logs, and manuals into the model's context.
Security Risk
Fine-tuning on sensitive data can be risky. RAG keeps your data in a secure Vector Database, never training the public model.
Verifiability
Hallucinations destroy trust. Our RAG systems provide Citations (Source Link + Page #) for every answer generated.
Advanced RAG Engineering Capabilities
Hybrid Search Architecture
Precision + Understanding.
- Combine Semantic Search (Vector embeddings) with Keyword Search (BM25).
- Capture specific product codes (Keywords) and broad concepts (Vectors).
Intelligent Document Processing (IDP)
Unstructured to Structured.
- Parse complex PDFs, tables, charts, and handwritten notes.
- Intelligent Chunking strategies (Parent-Child chunking) for context retention.
Re-Ranking & Optimization
The "Best Match" First.
- Implement Cross-Encoders (Re-rankers) to score search results.
- Filter out irrelevant noise before it reaches the LLM context window.
Vector Database Management
Scale to Billions.
- Architecture optimization for Pinecone, Weaviate, or Qdrant.
- Metadata filtering for RBAC (Role-Based Access Control) enforcement.
Citation & Grounding
Trust but Verify.
- Strict “Answer from Context Only” prompts.
- UI rendering of source PDFs highlighting the exact paragraph used.
Real-Time Indexing
Always Up-to-Date.
Event-driven pipelines (Kafka/Airflow) that update the Vector DB instantly when a source document changes.
The Retrieval Stack
High-performance infrastructure for your knowledge base.
Vector DBs

Pinecone

Weaviate

Qdrant

Milvus

Azure Search
Embeddings

OpenAI

Cohere

HuggingFace
Frameworks

LangChain

LlamaIndex

Haystack
Parsing

Unstructured.io

Amazon Textract

Azure Form Recognizer
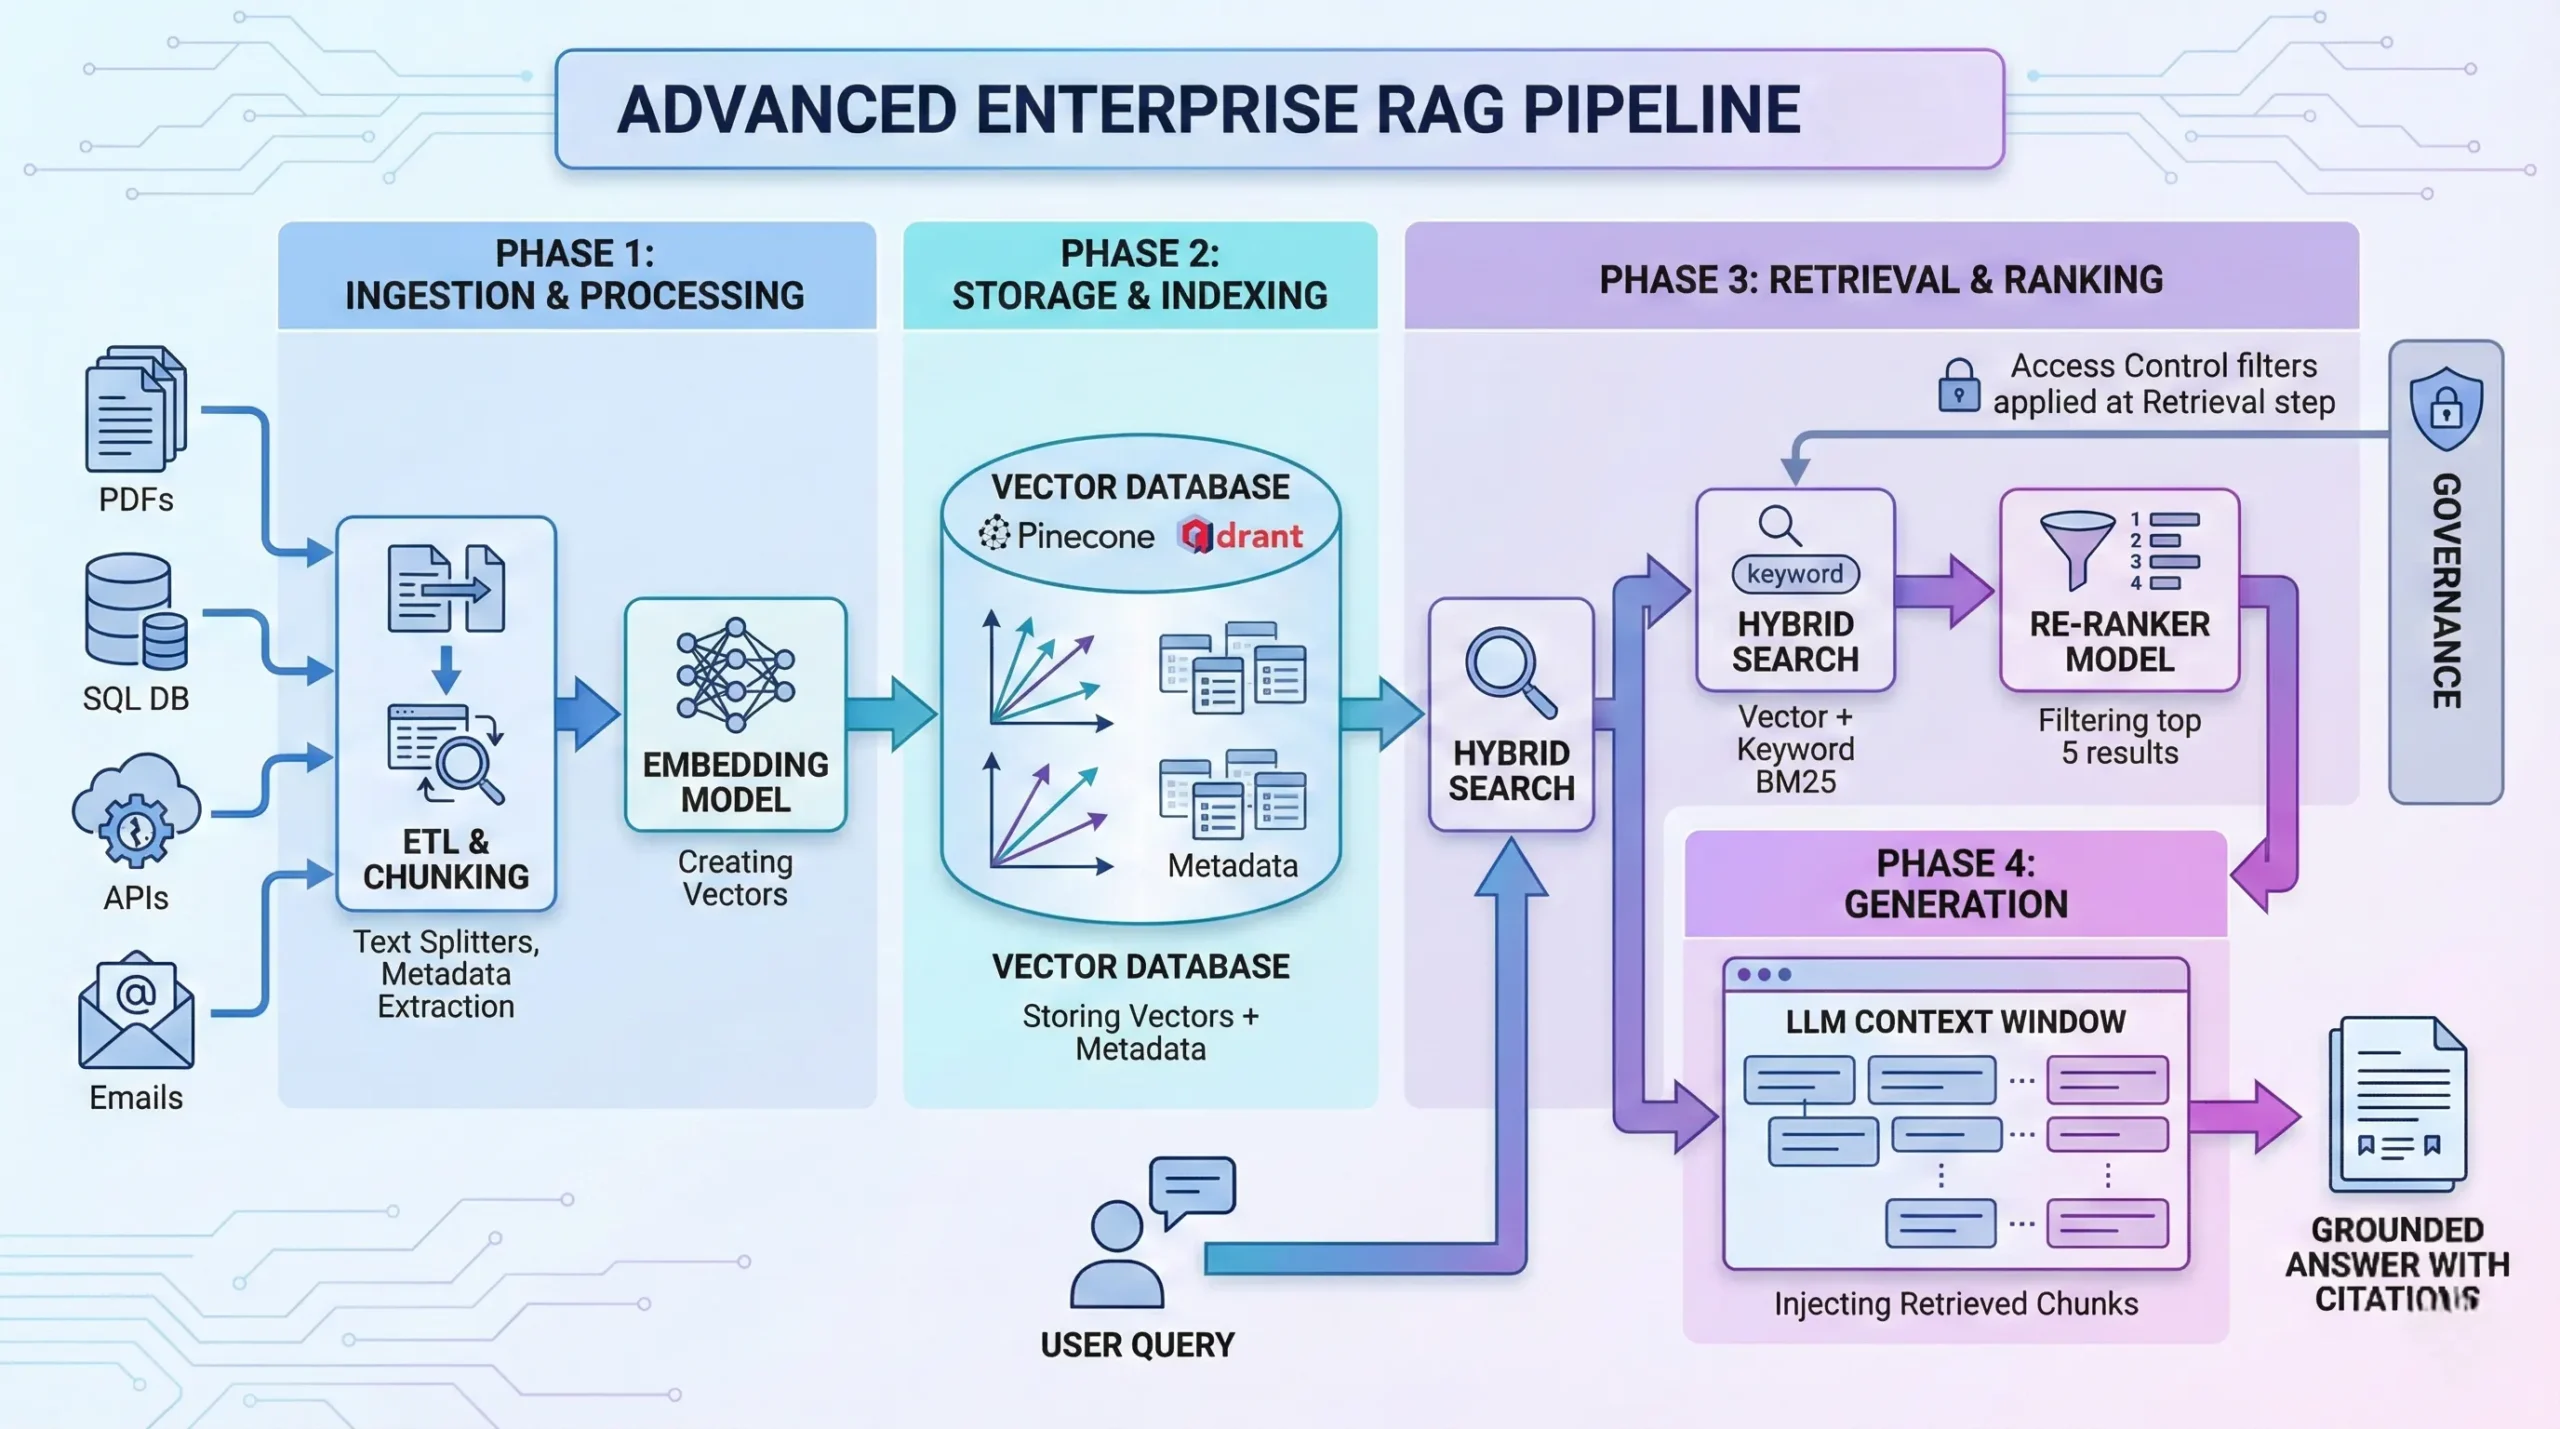
The "Advanced RAG" Pipeline
How we transform raw chaos into structured intelligence.
RAG in Production: Real Results
AI-Powered Legal Research Assistant for Indian Law & Documentation
AI-Powered Legal Research Assistant We partnered with a U.S.-based LegalTech firm to build a next-generation research platform. By fusing Retrieval-Augmented Generation (RAG) with Multi-Agent Orchestration (LangGraph), we created a system that analyzes thousands of case files, accelerating legal research by 70%. View System Architecture Explore Workflow automation The Impact Dashboard (Metrics) Faster Research Cycles […]
AI Background Removal Case Study
AI-Powered Background Removal for High Res Imagery We partnered with a Dubai-based photography automation firm to build a studio-grade segmentation engine. By combining Mask R-CNN for object detection with BiRefNet-HR for fine matting, we achieved hair-level precision on 8K images—without relying on restricted commercial models. View System Architecture Explore Computer Vision The Impact Dashboard […]
AI-Powered Person Re-Identification System
AI Powered Multi Camera Person Re Identification We partnered with a leading security technology provider in Saudi Arabia to build a next-generation surveillance platform. By fusing Face Embeddings, Gait Analysis, and Shoe Pattern Recognition, we engineered a system capable of tracking individuals across non-overlapping camera networks with high precision, even in crowded or low-light environments. […]
RAG Engineering Questions
How do you handle tables and charts in PDFs?
Standard text extraction fails here. We use Multi-Modal Parsing (using Vision models) to convert tables into markdown or structured JSON before embedding them, preserving the data context.
How secure is the Vector Database?
We use enterprise-tier Vector DBs (Pinecone Enterprise or Azure AI Search) that support Single Tenant deployment, encryption at rest, and PrivateLink connections.
How do you prevent the AI from answering questions it shouldn’t?
We implement RBAC (Role-Based Access Control) filters at the retrieval level. If a user doesn’t have permission to view a document, the RAG system won’t even retrieve it, so the LLM never sees it.